
Availability
 Users, Editors, and Admins
 All organizations and accounts
 Exclusive to select subscription plans
Merging datasets helps you combine related information from multiple sources into a single, unified dataset. By merging datasets, businesses can get a complete view of their performance, simplify reporting, improve data accuracy, and unlock deeper insights.
You can combine datasets in two ways:
- Join datasets adds the columns of one dataset next to another, matching rows that share the same values. Use this when each dataset describes the same records from a different angle, such as deals and the accounts they belong to.
- Stack datasets adds the rows of one dataset below another, pairing up the columns that hold the same kind of data. Use this when both datasets hold the same kind of records from different sources, such as video performance from two channels.
Before merging, make sure you have already created the datasets with all the columns you want to include, as you won't be able to add or modify columns during the merge process.
To open the merge flow, use one of the following options:
- Navigate to Data Manager > Merged datasets and click Merge datasets in the top right corner.
- Navigate to Data Manager > Datasets, locate the dataset you want to start from, click the drop-down arrow (
 ), and select Merge data.
- Open a dataset and click Merge data in the top right corner.
From there, follow these steps:
Click Select dataset, choose the first dataset you want to merge, and click Continue.
Select the columns you want to include from this dataset, then review the dataset preview.
Click
 Dataset above the preview table to add another dataset.
Select the second dataset, then choose the Merge type:
- Join datasets: choose the Join operator (Left outer, Inner, Right outer, or Full outer) and define the Join conditions by matching columns from each dataset.
- Stack datasets: review the Column mapping that pairs the new dataset's columns with the combined output. See Stack datasets for details.
The Output preview at the bottom shows how many rows the merged dataset returns.
Click Select to confirm the merge, then choose which columns from the second dataset you want to include.
Click Continue to review the preview of the merged dataset.
You can repeat steps 3–6 to merge additional datasets, up to a maximum of 20. Note that the final merged dataset can include up to 150 columns in total.

When merging datasets, Databox processes them from left to right in the list of datasets. This means:
- The left side of each join refers to either the first dataset or the result of all previous merges.
- The right side is the new dataset being merged at that step.
Here's a simple example:
Dataset A ➔ (merge with) ➔ Dataset B ➔ (merge with) ➔ Dataset C
- First, A is merged with B.
- Then, the result of (A + B) is merged with C.
When joining datasets, you can choose between four join operators depending on how you want to match and combine data:
| Join operator | Rows from left (first) dataset | Rows from right (second) dataset | Result |
|---|---|---|---|
 Left outer | All rows from the left dataset | Matching rows from the right dataset | Includes all left dataset rows, and matching rows from the right dataset. Non-matching rows from the right are excluded. |
 Inner | Only matching rows | Only matching rows | Includes only rows that have a match in both datasets. |
 Right outer | Matching rows from the left dataset | All rows from the right dataset | Includes all right dataset rows, and matching rows from the left dataset. Non-matching rows from the left are excluded. |
 Full outer | All rows from the left dataset | All rows from the right dataset | Includes all rows from both datasets. Non-matching rows will have null (empty) values where there's no match. |
When joining datasets, join conditions define how the datasets are matched together.
A join condition links a column from the left dataset to a column from the right dataset, based on matching values.
For example, if both datasets have a column called ID, you can create a join condition where ID from the left matches ID from the right. Only rows where the selected column values match will be joined together, depending on the join operator.
You can set one or more join conditions for each merge step. If you add multiple conditions, all conditions must be true for rows to match (similar to using "AND" logic in SQL).

- Use columns with unique or clearly matching values whenever possible (such as IDs, emails, or names).
- Avoid using columns with a lot of
nullor empty values, as this may lead to missing matches or unexpected results. - Make sure the data types of the columns you join on are compatible (e.g., both columns should be text, or both should be numbers).
Let's say you have two datasets:
Dataset A
| Region ID | Name | Sales |
|---|---|---|
| 1 | Alice | 100 |
| 2 | Bob | 150 |
| 3 | Charlie | 200 |
Dataset B
| Region ID | Region |
|---|---|
| 2 | East |
| 3 | West |
| 4 | South |
Before merging, you define a join condition that matches the Region ID column from the first dataset with the Region ID column from the second dataset. This ensures that rows with the same Region ID value are matched together during the merge.
Depending on the join operator you select (Left outer, Inner, Right outer, or Full outer), the resulting merged dataset will look different. See the examples for each join operator below.
Includes all rows from Dataset A, with matching Region values from Dataset B. Rows without a match in B have null values for Region.
| Region ID | Name | Sales | Region |
|---|---|---|---|
| 1 | Alice | 100 | null |
| 2 | Bob | 150 | East |
| 3 | Charlie | 200 | West |
Includes only rows where the Region ID exists in both datasets.
| Region ID | Name | Sales | Region |
|---|---|---|---|
| 2 | Bob | 150 | East |
| 3 | Charlie | 200 | West |
Includes all rows from Dataset B, with matching Name and Sales values from Dataset A. Rows without a match in A have null values for Name and Sales.
| Region ID | Name | Sales | Region |
|---|---|---|---|
| 2 | Bob | 150 | East |
| 3 | Charlie | 200 | West |
| 4 | null | null | South |
Includes all rows from both datasets. Missing values are shown as null.
| Region ID | Name | Sales | Region |
|---|---|---|---|
| 1 | Alice | 100 | null |
| 2 | Bob | 150 | East |
| 3 | Charlie | 200 | West |
| 4 | null | null | South |
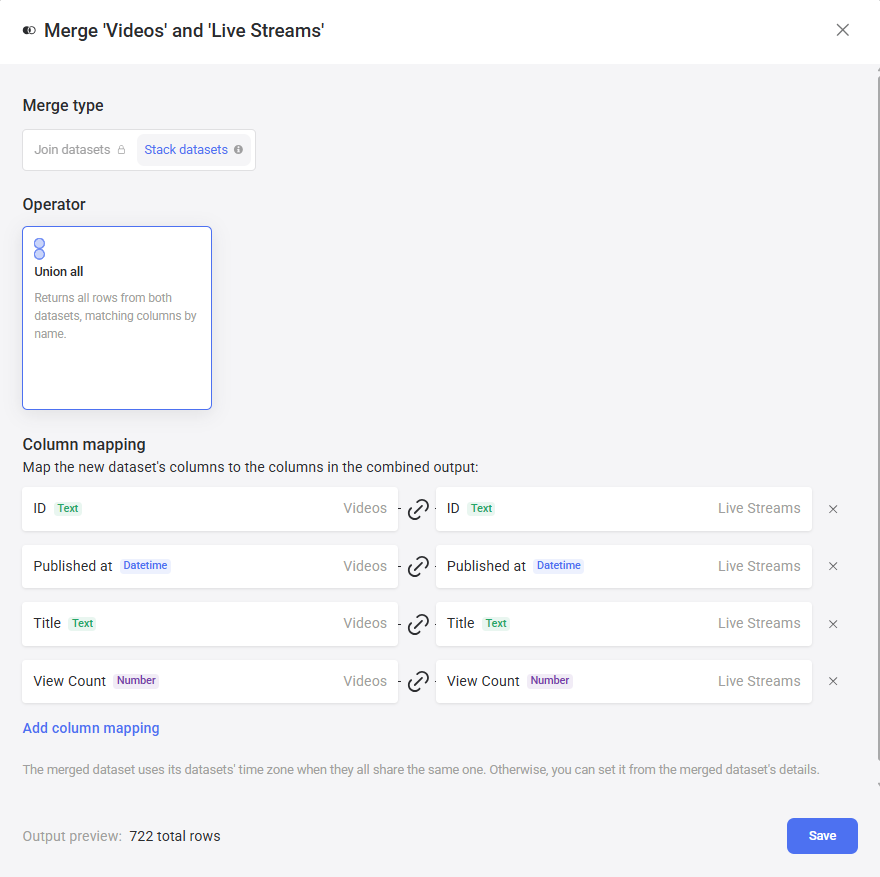
Stacking combines datasets vertically: the rows of the second dataset are added below the rows of the first, and you pair up the columns that hold the same kind of data. The columns don't need identical names, what matters is that they represent the same thing. The result has the columns of the first dataset and the combined row count of both.
Stacking uses a single operator, Union all, which returns all rows from both datasets. Duplicate rows are kept.
Column mapping defines which column in the new dataset feeds each column in the combined output.
Databox pairs columns automatically where the names and data types match. Where they don't, map them yourself:
- Click Add column mapping to pair another set of columns.
- Click the close icon next to a mapping to remove it.
Columns you don't map are excluded from the merged dataset. Once the mapping is set, click Save to confirm the stack.
- Map columns by what they represent, not by what they're called. A
Titlecolumn and aStream namecolumn belong together if both hold the name of the content. - Make sure the data types of the mapped columns match (text to text, number to number, datetime to datetime).
- Add a column that identifies the source of each row (such as a channel or region name) if you need to tell the stacked rows apart later.
- Check the Output preview row count before saving: it should equal the sum of the rows in both datasets.
Let's say you have two datasets that track the same kind of content under different column names:
Videos
| Title | View Count |
|---|---|
| Launch recap | 1,200 |
| Product demo | 850 |
Live Streams
| Stream name | Views |
|---|---|
| Q3 AMA | 400 |
| Office hours | 150 |
The column names differ, but they hold the same data: the name of the content and how many times it was watched. Mapping Stream name to Title and Views to View Count produces a single dataset with all four rows:
| Title | View Count |
|---|---|
| Launch recap | 1,200 |
| Product demo | 850 |
| Q3 AMA | 400 |
| Office hours | 150 |
FAQ
Can I merge datasets from different integrations?
Yes, you can merge datasets from different integrations as long as they have compatible join columns (e.g., matching IDs, names, or other common fields).
Can I use a merged dataset as an input in another merge?
Yes. Once you create and save a merged dataset, it becomes available alongside your other datasets. You can select it as an input when setting up a new merge, allowing you to build more complex datasets in multiple steps if needed.
Should I join or stack my datasets?
Join datasets when you want to add more columns to the same records, such as adding account details to a list of deals. Stack datasets when both datasets hold the same kind of records and you want them in one list, such as combining this year's and last year's orders.
What happens to columns I don't map when stacking?
Unmapped columns are left out of the merged dataset. Only the columns included in the column mapping appear in the combined output.
What happens if two datasets have columns with the same name?
If there are duplicate column names between datasets, Databox will automatically rename the columns during the merge to avoid conflicts (e.g., "Sales" and "Sales (2)").
Will merging datasets change my original datasets?
No. Merging datasets creates a new, separate dataset. Your original datasets remain unchanged.


